A used car pricing model works from what comparable units are listed and sold for, which is most of the answer. Five things it cannot see account for nearly all the mistakes — and each of them is something the person standing next to the car already knows.
This guide covers what market data captures, the five blind spots, how the human stays in the loop, where pricing tools fail, and what to measure.
What does the model actually see?
More than most people assume, and it is worth being precise about it.
A competent pricing model has access to: current listings for comparable units in a radius, recent sold transactions where available, days-on-market for similar vehicles, seasonal patterns by segment, and your own historical results if you feed them in. That is a genuinely good foundation and it beats a manager's recollection most of the time.
What it produces is a market position: where this unit sits against its competitive set today. That is the single most useful output in used car pricing, and it is the thing the manual repricing arithmetic fails to maintain at scale.
The five blind spots
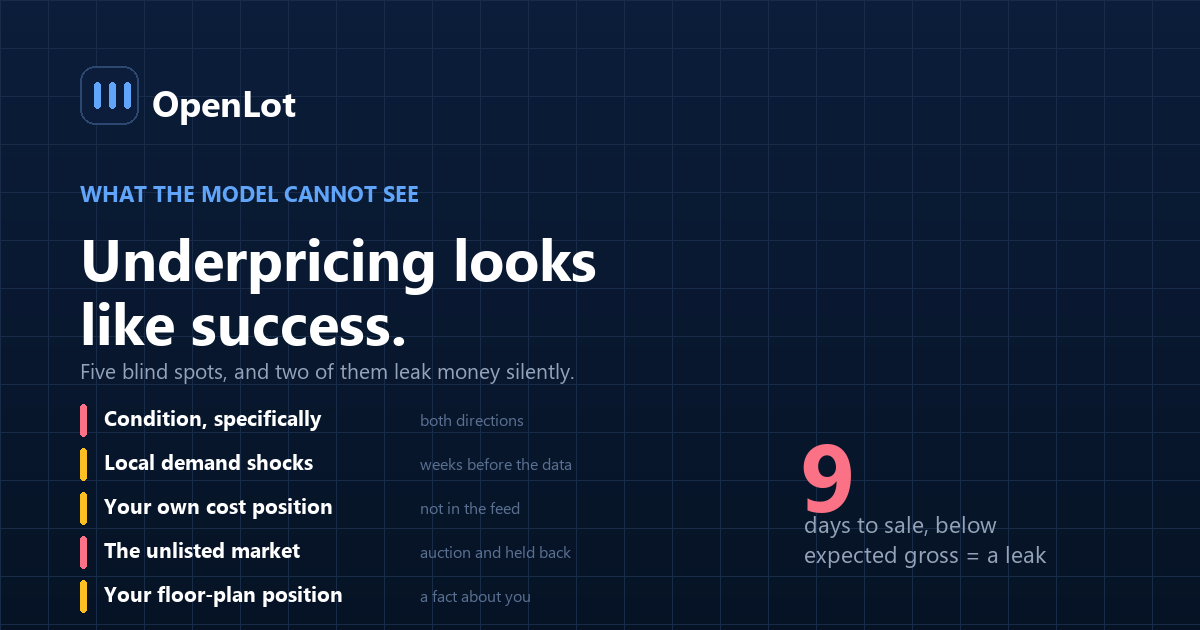
1. Condition, specifically. The model knows the year, trim and mileage. It does not know this unit has a repaint on the quarter panel, mismatched tyres, or an interior that photographs badly. Two identical-looking units can be $1,400 apart in reality and identical in the data.
2. Local demand shocks. A plant announcement, a change at a large local employer, a weather event. These move a specific market within days and appear in the data weeks later, if at all.
3. Your own cost position. The model prices to market. It does not know you bought this one well and can afford to turn it fast, or bought it badly and need the margin. Both are legitimate inputs to a price and neither is in the feed.
4. The competitive set that is not listed. Units at auction, units about to list, and the three comparable cars a competitor is holding back. The model sees the published market, which is not the whole market, and it is part of why forecasts decay so fast past 30 days.
5. Your floor-plan and cash position. Whether holding this unit for another three weeks is cheap or expensive right now is a business fact about your store, not about the car.
Where the money actually leaks
Illustrative. The point is the asymmetry.
Blind spot Typical error direction Cost when wrong Condition worse than average Priced too high Sits, ages, discounts later Condition better than average Priced too low Money left on the table, silently Local demand up Priced too low Sells fast, feels like success Local demand down Priced too high Ages, and nobody knows why Thin competitive set Priced too low The least visible of all Rows two and five are the dangerous ones, because underpricing looks like success. The unit sells in nine days, everyone is pleased, and nobody counts the money that was available.
How does the human stay in the loop?
Not by reviewing every price, which is the arithmetic that already failed. By reviewing the ones where the model is most likely to be wrong.
Flag by confidence, not by value. A pricing tool should express how thin the comparable set is. Units with few comparables are where a person adds the most.
Flag by condition deviation. If the recon cost on a unit was far above or below typical for its segment, the condition assumption is wrong and the price should be reviewed.
Flag by days-on-market divergence. A unit priced at market position that is not getting traffic after ten days is telling you the model missed something. That is a signal, not a discount trigger.
Review on acquisition, always. The first price is the one that sets the whole trajectory, and it is worth a person's attention every time.
Everything else can run on signals. This is the division that makes pricing tools work: the model maintains market position continuously, the manager intervenes where the model is uncertain or the evidence contradicts it.
Where do pricing tools fail?
1. Automatic price changes with no review. Confident mistakes at scale, and they compound because each change feeds the next comparison.
2. Priced to market when market is thin. Three comparables is not a market, and the model's confidence does not always fall far enough to say so.
3. Ignoring condition entirely. The single largest source of error, and it is solvable by feeding recon cost back in as a condition proxy — which also depends on measuring turn honestly.
4. Treating days-on-market as the only feedback. A unit can sit because of photographs, description or merchandising rather than price — and discounting a merchandising problem is expensive.
5. Never feeding results back. A model that does not learn from your own sold results stays generic, which is the main thing separating a useful tool from a market report.
6. Pricing a unit that should be wholesaled. Past a certain age the question is no longer the retail price, it is whether to retail it at all.
What should you measure?
| Metric | How to compute | What it catches |
|---|---|---|
| Price-to-market variance at sale | Sold price vs market position at the time | The honest accuracy measure |
| Gross variance by segment | Actual gross vs expected, split by vehicle type | Where the model is systematically off |
| Units sold under 14 days | Count, and their gross | Possible underpricing — check it |
| Days-on-market vs predicted | Actual vs modelled | Where condition or local demand was missed |
| Price changes per unit | From the feed | Whether signals are acted on at all |
| Recon cost vs segment average | Per unit | The condition proxy the model lacks |
Row three is the one stores never look at. Fast sales are assumed to be good, and a cluster of units selling in under two weeks at below-expected gross is the signature of systematic underpricing — a leak that produces no complaints and no aged inventory, which is exactly why it persists.
Frequently asked questions
What does an AI pricing model actually know about a used car?
The year, trim, mileage, and what comparable units are listed and sold for in a radius, plus days-on-market patterns and seasonality. That produces a market position, which is the most useful single output in used car pricing and the thing manual repricing cannot maintain past roughly 150 units.
What can a pricing model not see?
Condition specific to the unit, local demand shocks, your own cost position on that car, the competitive set that is not publicly listed, and your floor-plan situation. Each is something the person standing next to the vehicle already knows, which is why the human stays in the loop.
Should AI change used car prices automatically?
No. Automatic changes with no review produce confident errors at scale, and they compound because each change feeds the next comparison. The useful pattern is continuous market-position maintenance with human review on acquisition and on flagged exceptions.
How do you decide which prices a manager should review?
By exception rather than by value: units with few comparables, units whose recon cost diverged sharply from their segment average, units not getting traffic despite a correct market position, and every unit at acquisition. That keeps human attention where it adds the most.
Is underpricing a real risk with pricing tools?
Yes, and it is the one nobody catches. Underpriced units sell quickly, which feels like success, so nothing prompts a review. Tracking units sold in under two weeks alongside their gross is the way to surface it, because a cluster there at below-expected gross is the signature.
How does condition get into the model?
Imperfectly, and the best available proxy is recon cost against the segment average. A unit that cost far more or far less than typical to make front-line ready differs from the comparable set in a way the market data does not capture, and that is worth flagging for review.
What if a unit sits despite a correct market position?
Treat it as information rather than as a discount trigger. Photographs, description quality and merchandising all affect traffic independently of price, and discounting a merchandising problem is expensive. Check the listing before changing the number.
How do you tell whether the pricing tool is working?
Compare sold price against the market position it recommended at the time, split by segment, and track gross variance against expectation. A model that is systematically off in one vehicle category is usually missing something structural about that category rather than being wrong in general.
Conclusion
- The model produces market position, which is most of the answer and the part that cannot be maintained by hand.
- Five blind spots: condition, local demand, your cost position, the unlisted market, your floor plan.
- Underpricing looks like success, which is why it is the leak that persists.
- Review by exception: thin comparables, condition deviation, traffic that contradicts the position.
- Feed your own sold results back, or the tool stays a market report rather than a pricing system.
Last updated: